Showing posts with label google. Show all posts
Showing posts with label google. Show all posts
March 01, 2011
303
This is my last blog post here on blogger.com! You'll find my new thoughts, projects and development ramblings at http://dlinsin.github.com.
I migrated to blogger.com in late 2005 and was always quite happy with it. More than 5 years and exactly 502 posts later it's time to move on to something new.
Subscribe to my new blog feed, check my stuff on github or follow me on Twitter.
February 09, 2010
GWT @ JUG-Ka
 Tomorrow night there'll be the another event of the Java User Group Karlsruhe. It'll feature a talk on the Google Web Toolkit by Papick Taboada, who is quite an expert on the topic. The second part of the event will be a get-together after the talk, where you can discuss GWT over a beer. My company Synyx GmbH & Co. KG is kindly sponsoring the drinks.
The talk will take place at University Karlsruhe in room 101 and start at 7:15pm. The room is located in the basement, which you will find easily, if you follow our duke featured logo.
If you are interested in our lottery, where you can win a JetBrains or ZeroTurnaround license, submit your details through our online form. The winners are going to be announced at the end of the talk and must be present.
Last but not least, check us out on Twitter and subscribe to our Google Calendar or join our Xing Group.
October 05, 2009
Google Sitebricks
Last week I stumbled upon an interview on InfoQ with a Google developer working on a new web framework called Google Sitebricks. On my research day at Synyx, I had time to produce some sample code.
Google's mission statement goes as follows:
A Sitebrick based web-application is deployed as a good old WAR file in a servlet container. That's the first information not explicitly stated on the website. If you have worked with another web framework before, you probably know the concept of a controller or a REST-based Resource. You can find the same concept in Sitebricks, too:
You can see that the class is pretty simple and it reminds me a lot of Restlet, which I used extensively the past few months. With the At annotation you declare the Uri under which your resource should be available. You can also define variable parts in your Uri, e.g. /guestbook/:id, which is used in my sample to access an entry of the guestbook.
The methods annotated with Get and Post are being called upon a request with the corresponding method. If you take a closer look at the method load(), you can see, that it doesn't return any value. That's where the convention or should I call it magic, of the framework begins:
In your Html file, that you define along with your resource, there are expressions, that access members of your resource class. In the Html snippet above we iterate over a Collection named "entries". It's a member of the Guestbook class and is assigned whenever there's a Get request, which triggers the method load() to be called. The expression items=entries calls the getEntries() method on Guestbook, to return the Collection.
Frankly, this strikes me kinda odd. You call a method to populate a member and then its getter to retrieve the value? Shouldn't the annotated Get method return the value directly? I'm not quite sure what the design goal was here, but the first thing that comes into my mind is concurrency. If your resource class is a Singleton, you could run into quite some trouble.
Take a look at the form in the Html snipped above. It has two input fields, which are properties, mapped by name to the member newEntry. The member must be accessible under the resource declared in the action attribute of the form. This was not mentioned in the Sitebrick docs either. When you submit the form, the getNewEntry() method is called and the input field values are set at the returned instance. After that, the annotated save() method is called with the member newEntry already populated.
Again, the design here is rather unusual. You are working on a member, which in case of a Singleton resource, means there is shared state. Of course, if you define your resources not as Singleton, you don't have any problems. However, it's definitely a pitfall, in my opinion.
Overall, I think Google Sitebricks contains a couple of cool ideas. I like the expression language kind of approach, which makes it easy to work with Html snippets. The possibility to define little components (Bricks) and add them in other sites, is another really cool feature.
The project is still in its early stages and I hope they'll address those odd design decisions, mentioned above. Although it's not standards-based, with Google backing the framework, I could imagine Sitebricks getting some traction.
Google's mission statement goes as follows:
Sitebricks is a simple development layer for web applications built on top of Google Guice. Sitebricks focuses on early error detection, low-footprint code, and fast development. Like Guice, it also balances idiomatic Java with an emphasis on concise code.
A Sitebrick based web-application is deployed as a good old WAR file in a servlet container. That's the first information not explicitly stated on the website. If you have worked with another web framework before, you probably know the concept of a controller or a REST-based Resource. You can find the same concept in Sitebricks, too:
You can see that the class is pretty simple and it reminds me a lot of Restlet, which I used extensively the past few months. With the At annotation you declare the Uri under which your resource should be available. You can also define variable parts in your Uri, e.g. /guestbook/:id, which is used in my sample to access an entry of the guestbook.
The methods annotated with Get and Post are being called upon a request with the corresponding method. If you take a closer look at the method load(), you can see, that it doesn't return any value. That's where the convention or should I call it magic, of the framework begins:
In your Html file, that you define along with your resource, there are expressions, that access members of your resource class. In the Html snippet above we iterate over a Collection named "entries". It's a member of the Guestbook class and is assigned whenever there's a Get request, which triggers the method load() to be called. The expression items=entries calls the getEntries() method on Guestbook, to return the Collection.
Frankly, this strikes me kinda odd. You call a method to populate a member and then its getter to retrieve the value? Shouldn't the annotated Get method return the value directly? I'm not quite sure what the design goal was here, but the first thing that comes into my mind is concurrency. If your resource class is a Singleton, you could run into quite some trouble.
Take a look at the form in the Html snipped above. It has two input fields, which are properties, mapped by name to the member newEntry. The member must be accessible under the resource declared in the action attribute of the form. This was not mentioned in the Sitebrick docs either. When you submit the form, the getNewEntry() method is called and the input field values are set at the returned instance. After that, the annotated save() method is called with the member newEntry already populated.
Again, the design here is rather unusual. You are working on a member, which in case of a Singleton resource, means there is shared state. Of course, if you define your resources not as Singleton, you don't have any problems. However, it's definitely a pitfall, in my opinion.
Overall, I think Google Sitebricks contains a couple of cool ideas. I like the expression language kind of approach, which makes it easy to work with Html snippets. The possibility to define little components (Bricks) and add them in other sites, is another really cool feature.
The project is still in its early stages and I hope they'll address those odd design decisions, mentioned above. Although it's not standards-based, with Google backing the framework, I could imagine Sitebricks getting some traction.
August 10, 2009
Cron Jobs on Google App Engine
I've been developing for the Google App Engine (GAE) for a couple of months now and there's a lot, I want to talk about in future blog posts. This installment is about scheduled tasks on the GAE - cron jobs - and a couple of pitfalls that you should be aware of.
The configuration of a cron on GAE is pretty straightforward. You define your job in a file called cron.xml, which goes to your WEB-INF folder in your WAR file.
The file is easy to understand: url denotes where the GAE is supposed to send a GET request to, when the cron is triggered. Whatever you place behind the denoted url is your own choice. It can be a plain Servlet or some RESTful resource. The schedule tag contains a english-like syntax to define when the url is supposed to be requested. In this example GAE makes a HTTP GET request to http://yourname.appspot.com/cron/clean every 5 minutes.
One of GAE's subtle details is that your application is being shutdown, as soon as there are no requests coming in for a certain period of time. That's no a problem by itself, however, if you want to access the cached data of your application from within your cron, you are in trouble. It's not a severe problem, you just need prepared for it.
Another pitfall, that you might encounter, is configuring the url of the cron to be secured by SSL. You can define which urls are supposed to be confidential in your web.xml. As soon as you add your cron's url, you'll encounter an error message in your admin console under "Cron Jobs", which says "Too many continues". This indicates, that GAE wants to execute cron jobs using http instead of https, which leads to a HTTP 302 response. Browsers can easily interpret it as "don't use http, use https instead", but the GAE can't.
This is not a security problem, since the urls of your cron job should only be accessible by administrators anyways. You can easily exclude the cron's url from your SSL configuration and everything should work fine.
There are more little gotchas, that I encountered developing for the GAE and I'm going to blog more about it soon.
The configuration of a cron on GAE is pretty straightforward. You define your job in a file called cron.xml, which goes to your WEB-INF folder in your WAR file.
<?xml version="1.0" encoding="UTF-8"?>
<cronentries>
    <cron>
        <url>/cron/clean</url>
        <description>job to clean tmp every 5 minutes</description>
        <schedule>every 5 minutes</schedule>
    </cron>
</cronentries>
The file is easy to understand: url denotes where the GAE is supposed to send a GET request to, when the cron is triggered. Whatever you place behind the denoted url is your own choice. It can be a plain Servlet or some RESTful resource. The schedule tag contains a english-like syntax to define when the url is supposed to be requested. In this example GAE makes a HTTP GET request to http://yourname.appspot.com/cron/clean every 5 minutes.
One of GAE's subtle details is that your application is being shutdown, as soon as there are no requests coming in for a certain period of time. That's no a problem by itself, however, if you want to access the cached data of your application from within your cron, you are in trouble. It's not a severe problem, you just need prepared for it.
Another pitfall, that you might encounter, is configuring the url of the cron to be secured by SSL. You can define which urls are supposed to be confidential in your web.xml. As soon as you add your cron's url, you'll encounter an error message in your admin console under "Cron Jobs", which says "Too many continues". This indicates, that GAE wants to execute cron jobs using http instead of https, which leads to a HTTP 302 response. Browsers can easily interpret it as "don't use http, use https instead", but the GAE can't.
This is not a security problem, since the urls of your cron job should only be accessible by administrators anyways. You can easily exclude the cron's url from your SSL configuration and everything should work fine.
There are more little gotchas, that I encountered developing for the GAE and I'm going to blog more about it soon.
May 25, 2009
Make it Easy to Contribute
The past couple of weeks, I've been playing a lot with Restlet, a Java based REST framework. I like the it a lot, because it's easy to use and you can get it up and running in no time.
The current version of Restlet is 1.1, but when I compared it to the upcoming version 1.2-M2. it was clear that I would start using that right away. It has built in Google App Engine support and uses an Annotation driven approach, which increases testability and ease of use. This is one of the rare uses cases, where I think Annotations are perfectly suited, but I'm digressing. Overall, it was a natural choice to use the milestone build 1.2 right from the beginning.
After a couple of weeks of coding against 1.2-M2, I started to encounter a couple of weird side effects. After testing the code against the current stable version, it was clear, that it must be a bug in the 1.2 milestone release. So I checked the Restlet site, which nicely describes the process of reporting bugs.
As a decent developer, I followed the link to the issue tracker and saw this:
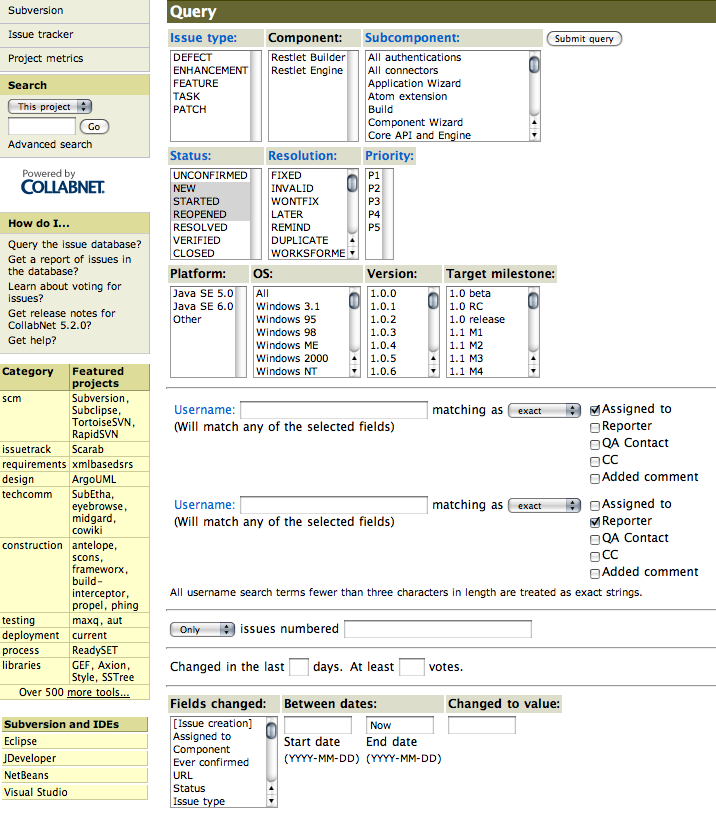
I was shocked to see this kind of interface! I know I'm a developer and I should love these kind of fine grained and detailed options to query an issues tracker, but that's too much! It's not the first time that I see this interface, Java.net uses it too and I just think it's a PITA to use! Compare it to google's code hosting issue tracker interface:
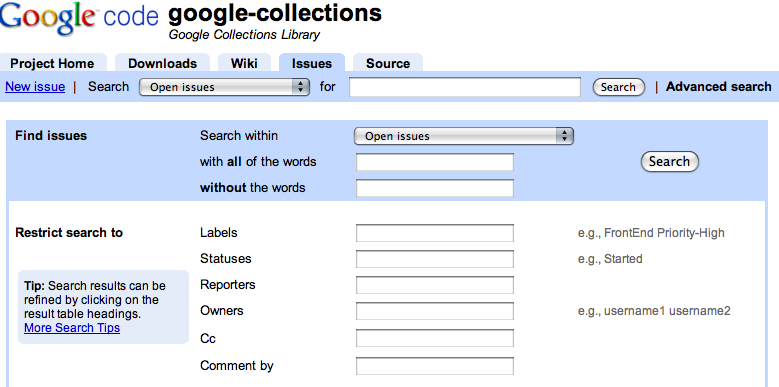
It's worlds apart in terms of usability and ease of use! And the screenshot above even shows the "advanced" search mode. In most cases, you can find everything with a single search box - google like!
I think, if you want the community to interact and contribute to your project, make it as easy as possible for them. They are trying to help you! We all know the problem of issues reported multiple times or reporters not taking time to correctly file an issue. However, every feedback is valuable and you can always ask for further and more detailed descriptions, if necessary.
Coming back to my bug in Restlet, after I managed to query the issue tracker, I saw that it had already been reported. So I decided to switch back to the current stable version. Unfortunately, I had to jump through a couple of hoops to make it work on the GAE, but that's another story altogether.
The current version of Restlet is 1.1, but when I compared it to the upcoming version 1.2-M2. it was clear that I would start using that right away. It has built in Google App Engine support and uses an Annotation driven approach, which increases testability and ease of use. This is one of the rare uses cases, where I think Annotations are perfectly suited, but I'm digressing. Overall, it was a natural choice to use the milestone build 1.2 right from the beginning.
After a couple of weeks of coding against 1.2-M2, I started to encounter a couple of weird side effects. After testing the code against the current stable version, it was clear, that it must be a bug in the 1.2 milestone release. So I checked the Restlet site, which nicely describes the process of reporting bugs.
Before entering a new report, you should query the current issue database for similar open issues.
As a decent developer, I followed the link to the issue tracker and saw this:
I was shocked to see this kind of interface! I know I'm a developer and I should love these kind of fine grained and detailed options to query an issues tracker, but that's too much! It's not the first time that I see this interface, Java.net uses it too and I just think it's a PITA to use! Compare it to google's code hosting issue tracker interface:
It's worlds apart in terms of usability and ease of use! And the screenshot above even shows the "advanced" search mode. In most cases, you can find everything with a single search box - google like!
I think, if you want the community to interact and contribute to your project, make it as easy as possible for them. They are trying to help you! We all know the problem of issues reported multiple times or reporters not taking time to correctly file an issue. However, every feedback is valuable and you can always ask for further and more detailed descriptions, if necessary.
Coming back to my bug in Restlet, after I managed to query the issue tracker, I saw that it had already been reported. So I decided to switch back to the current stable version. Unfortunately, I had to jump through a couple of hoops to make it work on the GAE, but that's another story altogether.
April 16, 2009
More Playing with GAE
In my previous blog about the Google App Engine (GAE), I wrote about the problems I had encountered using JPA and Maven. In this post I want to share how using Groovy on the GAE worked out and what my impressions are on the scalability of the platform.
Inspired by SpringSource's blog on Groovy with the GAE and after almost a year, I decided to do some Groovy coding. I wrote a small Groovlet, which uses the JPA to fetch entities from persistent storage. Again, I'm quite astonished of how smooth coding can be:
To be fair, I have no Exception handling in this code and there is no finally making sure the EntitManager is closed at the end. Yet, it feels like Java without the clutter.
To get this working on the GAE, all you need to do is drop the groovy-all.jar into the WEB-INF/lib folder of your WAR file and add the GroovyServlet to your web.xml. You add your Groovlet to a groovy folder under WEB-INF and access it like a good old Servlet in your browser e.g. http://dlinsin-area51.appspot.com/HelloWorld.groovy.
Unfortunately there is one major drawback, which makes developing Groovy for GAE a real pain - local deployment of Groovlets is not working right now. It seems like Google has been notified about the issue, but even after a few days the bug is still in status "new", so I don't think there'll be a fix anytime soon. Since daily deployment is limited by a quota, I think this bug is almost a show-stopper and I wouldn't want to develop in Groovy for the GAE right now.
Let's turn our attention to performance and scalability. First off I have a disclaimer: I didn't run any thorough or scientific tests! Although I have some numbers to back up my opinion, you might want to run further tests before you draw a final conclusion.
To get us all on the same page, let's start with a little "theory". When I talk about performance it means something like this:
The same goes for scalability, although in general it's more subtle to properly define it:
With that out of the way let's head over to the test setup. It consists of a simple Apache JMeter test script, which puts my poor sample application under load. The script loads the start page http://dlinsin-area51.appspot.com, then inserts the name "JMeter" into the input field and submits the form. The submission results in a redirect to the start page again. I mainly wanted to test "writes" to the persistent storage, because in my experience that's the most hardest part to scale.


I ran the test script with 10 threads (blue shaded) and with 100 threads hitting my sample app. Each thread runs the test procedure 10 times. The results were quite interesting. If you take a closer look at the average response time of both samplers you can see only a small difference between 10 users and 100 users (or threads) hitting the application at the same time. The response time for inserting a row into the persistent storage went up insignificantly, which I think is quite astonishing, considering the increase of load.
However, you should take these results with a grain of salt. They merely exist to give me a hint of what the GAE is capable of. I would be interested in real benchmarks, because I think it's crucial to see how scalable the GAE is under field conditions.
Update: The test results are simply wrong! Thx for pointing it out Bernd, I'm working on it!
Update 2: Here comes the bugfix!


You might ask what happened? Frankly, I mixed up the pictures and didn't double check, before pushing out the post. Sorry about that! I ran the tests with the same specs as mentioned above again and as you can see from the results, this time it looks reasonable.
Based on the new numbers, I have to put my conclusion a little bit into perspective. It still think the GAE scales reasonably well, but the numbers are not that astonishing anymore.
Inspired by SpringSource's blog on Groovy with the GAE and after almost a year, I decided to do some Groovy coding. I wrote a small Groovlet, which uses the JPA to fetch entities from persistent storage. Again, I'm quite astonished of how smooth coding can be:
import javax.persistence.*
import java.util.List
import de.linsin.sample.gae.domain.User
import de.linsin.sample.gae.EMF

EntityManager em = EMF.getInstance().createEntityManager()
Query query = em.createQuery("SELECT u FROM " + User.class.getName() + " u")
List<User> users = query.getResultList()

for (User user : users) {
  out.println(user.getName() + " " + user.getLastname() + "<br/>")
}

em.close();
To be fair, I have no Exception handling in this code and there is no finally making sure the EntitManager is closed at the end. Yet, it feels like Java without the clutter.
To get this working on the GAE, all you need to do is drop the groovy-all.jar into the WEB-INF/lib folder of your WAR file and add the GroovyServlet to your web.xml. You add your Groovlet to a groovy folder under WEB-INF and access it like a good old Servlet in your browser e.g. http://dlinsin-area51.appspot.com/HelloWorld.groovy.
Unfortunately there is one major drawback, which makes developing Groovy for GAE a real pain - local deployment of Groovlets is not working right now. It seems like Google has been notified about the issue, but even after a few days the bug is still in status "new", so I don't think there'll be a fix anytime soon. Since daily deployment is limited by a quota, I think this bug is almost a show-stopper and I wouldn't want to develop in Groovy for the GAE right now.
Let's turn our attention to performance and scalability. First off I have a disclaimer: I didn't run any thorough or scientific tests! Although I have some numbers to back up my opinion, you might want to run further tests before you draw a final conclusion.
To get us all on the same page, let's start with a little "theory". When I talk about performance it means something like this:
... performance is characterized by the amount of useful work accomplished by a computer system compared to the time and resources used.
...performance may involve one or more of the following:Short response time High throughput
The same goes for scalability, although in general it's more subtle to properly define it:
...scalability is a desirable property of a system, a network, or a process, which indicates its ability to either handle growing amounts of work in a graceful manner, or to be readily enlarged.
With that out of the way let's head over to the test setup. It consists of a simple Apache JMeter test script, which puts my poor sample application under load. The script loads the start page http://dlinsin-area51.appspot.com, then inserts the name "JMeter" into the input field and submits the form. The submission results in a redirect to the start page again. I mainly wanted to test "writes" to the persistent storage, because in my experience that's the most hardest part to scale.
I ran the test script with 10 threads (blue shaded) and with 100 threads hitting my sample app. Each thread runs the test procedure 10 times. The results were quite interesting. If you take a closer look at the average response time of both samplers you can see only a small difference between 10 users and 100 users (or threads) hitting the application at the same time. The response time for inserting a row into the persistent storage went up insignificantly, which I think is quite astonishing, considering the increase of load.
However, you should take these results with a grain of salt. They merely exist to give me a hint of what the GAE is capable of. I would be interested in real benchmarks, because I think it's crucial to see how scalable the GAE is under field conditions.
Update: The test results are simply wrong! Thx for pointing it out Bernd, I'm working on it!
Update 2: Here comes the bugfix!
You might ask what happened? Frankly, I mixed up the pictures and didn't double check, before pushing out the post. Sorry about that! I ran the tests with the same specs as mentioned above again and as you can see from the results, this time it looks reasonable.
Based on the new numbers, I have to put my conclusion a little bit into perspective. It still think the GAE scales reasonably well, but the numbers are not that astonishing anymore.
April 13, 2009
Playing with Google App Engine
I'm jumping on the hype wagon and checking out the Google App Engine (GAE) for Java. After writing a simple sample application using Servlets, Groovlets and the JPA, I want to share with you the bumpy ride I had.
If you are interested in checking out the sample application you can either download it or check it out on github.
Fankly, I only had a bumpy ride, because I didn't follow Google's suggestion to use the Eclipse IDE plug-in together with a set of ANT tasks, they provide. Instead I wanted to use IntelliJ and Maven. Another suggestions of Google I didn't follow, is to use Java Data Object (JDO) as a persistence API. Yes, that's right, Google suggests JDO as a preferred way to store data. If you are working on a somewhat up to date Java enterprise application, you are probably using the Java Persistence API (JPA) instead. The difference between the two standards, according to wikipedia, are:
Google's underlying persistence layer is called Bigtable. It's designed to scale across distributed systems, by being non-relation. That means you can dump your data into Bigtable, without brooding over your schema first. On the question why Google favors JDO over JPA, I think it's because you are not dealing with an RDBMS, but Bigtable.
The first thing I did was to write a simple hello world JSP and Servlet and packaged it as a WAR file. Thanks to IntelliJ's built-in enterprise support, I was up and running in no more than 10 minutes. The only difference to a regular enterprise application is the file appengine-web.xml. It contains your application identifier and version. The versioning schema is quite interesting. You can configure which version a user sees and simultaneously deploy a new version for testing.
Google provides a couple of command-line tools, which help you to start a local version of the app engine and upload your application to the cloud. Once you are online, you can access your server logs through a dashboard. Unfortunately I wasn't able to see the logs instantly, after encountering errors. I had to wait for a couple of seconds, which is pretty annoying and makes local testing much more important.
The first hurdle I had to overcome was integrating JPA. Google uses an implementation called DataNucleus, which relies on post-compile bytecode manipulation of your entities. I had the hardest time integrating the bytecode manipulation with my Maven build. Fortunately, the App Engine Google Group was very helpful and the problem was solved quickly. After a couple of hours, I was able to run my first JPA enabled application, without thinking about deployment or database issues. No problems with getting a server to run or twiddling with database settings - the stuff just runs.
As a developer, your probably don't want be bothered with infrastructure, which sometimes looks like black magic. I really like the completely transparent way of developing for the GAE, but I'm skeptical if I'd want to rely my business on this kind of hosting. With Amazon's EC2 you still have the configuration of the system under control and that's probably important, if you want to run a business on it. In terms of pricing, I can't really say much. To me it looks almost the same, except that with GAE you have a quota on everything. There's even a daily quota on datastore API calls, which can't be increased even by paying for it. That's a bit of a bummer! However, I think they chose the quotas reasonably and maybe the are being increased after the public release of the GAE for Java.
In my next blog post, I will cover some more details on how to run Groovlets. I also did some simple load testing with Apache JMeter to get a feeling on how GAE scales.
If you are interested in checking out the sample application you can either download it or check it out on github.
Fankly, I only had a bumpy ride, because I didn't follow Google's suggestion to use the Eclipse IDE plug-in together with a set of ANT tasks, they provide. Instead I wanted to use IntelliJ and Maven. Another suggestions of Google I didn't follow, is to use Java Data Object (JDO) as a persistence API. Yes, that's right, Google suggests JDO as a preferred way to store data. If you are working on a somewhat up to date Java enterprise application, you are probably using the Java Persistence API (JPA) instead. The difference between the two standards, according to wikipedia, are:
... JPA, however, is an Object-relational mapping (ORM) standard, while JDO is an Object-relational mapping standard and a transparent object persistence standard. JDO, from an API point of view, is agnostic to the technology of the underlying datastore, whereas JPA is being oriented totally around RDBMS datastores.
Google's underlying persistence layer is called Bigtable. It's designed to scale across distributed systems, by being non-relation. That means you can dump your data into Bigtable, without brooding over your schema first. On the question why Google favors JDO over JPA, I think it's because you are not dealing with an RDBMS, but Bigtable.
The first thing I did was to write a simple hello world JSP and Servlet and packaged it as a WAR file. Thanks to IntelliJ's built-in enterprise support, I was up and running in no more than 10 minutes. The only difference to a regular enterprise application is the file appengine-web.xml. It contains your application identifier and version. The versioning schema is quite interesting. You can configure which version a user sees and simultaneously deploy a new version for testing.
Google provides a couple of command-line tools, which help you to start a local version of the app engine and upload your application to the cloud. Once you are online, you can access your server logs through a dashboard. Unfortunately I wasn't able to see the logs instantly, after encountering errors. I had to wait for a couple of seconds, which is pretty annoying and makes local testing much more important.
The first hurdle I had to overcome was integrating JPA. Google uses an implementation called DataNucleus, which relies on post-compile bytecode manipulation of your entities. I had the hardest time integrating the bytecode manipulation with my Maven build. Fortunately, the App Engine Google Group was very helpful and the problem was solved quickly. After a couple of hours, I was able to run my first JPA enabled application, without thinking about deployment or database issues. No problems with getting a server to run or twiddling with database settings - the stuff just runs.
As a developer, your probably don't want be bothered with infrastructure, which sometimes looks like black magic. I really like the completely transparent way of developing for the GAE, but I'm skeptical if I'd want to rely my business on this kind of hosting. With Amazon's EC2 you still have the configuration of the system under control and that's probably important, if you want to run a business on it. In terms of pricing, I can't really say much. To me it looks almost the same, except that with GAE you have a quota on everything. There's even a daily quota on datastore API calls, which can't be increased even by paying for it. That's a bit of a bummer! However, I think they chose the quotas reasonably and maybe the are being increased after the public release of the GAE for Java.
In my next blog post, I will cover some more details on how to run Groovlets. I also did some simple load testing with Apache JMeter to get a feeling on how GAE scales.
February 09, 2009
Got Burned, Changing my feed!!
My current feed is run by FeedBurner. That means most of you are getting this feed from http://feeds.feedburner.com/dlinsin and thanks to FeedBurner you see stuff like "Digg This!" or "Submit to Reddit" at the bottom of each post.
FeedBurner was acquired by Google and is moving all accounts to Google Adsense by the end of this month. Since Google doesn't want me to use Adsense, I can only switch back to my old feed. So if you want to keep reading my stuff, simply switch to http://dlinsin.blogspot.com/feeds/posts/default/. However, the FeedBurner feed will still be alive for the next couple of weeks.
FeedBurner was acquired by Google and is moving all accounts to Google Adsense by the end of this month. Since Google doesn't want me to use Adsense, I can only switch back to my old feed. So if you want to keep reading my stuff, simply switch to http://dlinsin.blogspot.com/feeds/posts/default/. However, the FeedBurner feed will still be alive for the next couple of weeks.
November 21, 2007
November 14, 2007
Google's Dalvik VM
According to Stefano Mazzocchi Google came up with the own non-standard VM called Dalvik:
The fact that this VM is not a Java Platform, but is using something similar to Java is the first step towards a messy future for Java developers. If you can't rely on the platform to behave the same way Java does, you'll never know what's gonna happen if you run your code on a non-standard VM. Imagine if you use a standard Java class like java.lang.String and it behaves differently on other VMs. It'd would be a nightmare to debug code, since everything you implement is an assumption! An assumption that it behaves the same way the Java Platform does. That's not really what developers want.
That was me speaking as a Java developer. As a consumer and technology fan, I think it's brilliant that Google fosters competition! Finally something is happening in the mobile phone application section. There are great Java ME applications like Google's Maps and GMail, but you never know if they work on your phone. Basically every phone behaves differently. If Google manages to unify handset manufactures to commit to a standard platform, even if it's not the Java platform, it's the right move.
Dalvik has been written so that a device can run multiple VMs efficiently and relies on the Linux kernel for underlying functionality such as threading and low-level memory management. It executes files in the Dalvik Executable (.dex) format which is optimized for minimal memory footprint. The VM is register-based, and runs classes compiled by a Java language compiler that have been transformed into the .dex format by the included "dx" tool .... It is a departure from a traditional JVM in that it runs it's own variant of byte-code. It supports a language similar to Java with a lot of the common Java API's based on Apache Harmony and runs in a traditional IDE. It just compiles to a different byte-code.This caused a lot of buzz, like everything Google does, but I think it can have quite an impact on the Java world. I have not looked into Android, nor have I read anything else but speculations so I'll just continue and add more thoughts based on assumptions.
The fact that this VM is not a Java Platform, but is using something similar to Java is the first step towards a messy future for Java developers. If you can't rely on the platform to behave the same way Java does, you'll never know what's gonna happen if you run your code on a non-standard VM. Imagine if you use a standard Java class like java.lang.String and it behaves differently on other VMs. It'd would be a nightmare to debug code, since everything you implement is an assumption! An assumption that it behaves the same way the Java Platform does. That's not really what developers want.
That was me speaking as a Java developer. As a consumer and technology fan, I think it's brilliant that Google fosters competition! Finally something is happening in the mobile phone application section. There are great Java ME applications like Google's Maps and GMail, but you never know if they work on your phone. Basically every phone behaves differently. If Google manages to unify handset manufactures to commit to a standard platform, even if it's not the Java platform, it's the right move.
November 07, 2007
Google Mail 2.0
A couple of weeks ago Google Blogoscoped reported about a new Gmail UI, which improves contact organization. This morning I was surprised to see it enabled in my Gmail account, especially after waiting forever to get IMAP. It looks really slick, especially the new box that pops up when you hover a contact on your chat list.


October 11, 2007
September 21, 2007
Google's spell checker rocks
Yesterday I blogged about James Gosling and I accidental spelled his name wrong as Google's spell checker told me.

I think this is amazing! Think about it, it does present me the correct suggestion of James Gosling's name. Okay it's a pretty well known name, I give you that. For instance it doesn't suggest correct alternatives to my misspelled name, not yet :-). But I still think this is really cool and very helpful.

I think this is amazing! Think about it, it does present me the correct suggestion of James Gosling's name. Okay it's a pretty well known name, I give you that. For instance it doesn't suggest correct alternatives to my misspelled name, not yet :-). But I still think this is really cool and very helpful.
September 20, 2007
September 13, 2007
Listphile
 Yesterday I checked out the new site Listphile, which offers you a Google Base like web 2.0 application to create and share multimedia lists. You can read a short analyzes of the site over at TechCrunch.
I really like the site, but I can't think of a use case without having an API. Maybe my sentiment about applications like Listphile are mostly driven by thinking too much like a software engineer. Or maybe I'm just too lazy to submit data by hand, I don't know. At least I could think of something to do with Listphile, if I had an API to fill a list with data.
As a side note, I really like that they have an openid integration, so there is no need to setup another account and create another profile!
September 11, 2007
Accomplishing more by doing less
At a talk at Google, Marc Lesser says with the following practices you can accomplish more by doing less:
- retreat to get ahead
- investigate reality
- create routines that mint gold
- communication matters
- small changes for big results
- integrative thinking
- asking dumb or penetrating questions
September 06, 2007
New Google Reader interface
I had this Google Reader interface yesterday morning already, but after a while it disappeared. Now it's either finally live or I get the chance to have another test run.

The tree view navigation can be minimized now so you have almost the full screen to read your feed.

The search feature lets you search through all or selected folders. It's amazingly fast and searches unread and read feed items as well.

Does anyone else have this interface too?

The tree view navigation can be minimized now so you have almost the full screen to read your feed.

The search feature lets you search through all or selected folders. It's amazingly fast and searches unread and read feed items as well.

Does anyone else have this interface too?

